Environment innovation
Long-horizon coalition strategy with 7 action types, 4 factions, 4 sectors, partial observability and a 5-gate composable rubric.
Neon Syndicate is a cinematic OpenEnv environment where an LLM negotiates coalitions, scouts sectors, executes a coded operation, and extracts — all under partial observability. Most benchmarks reward one good answer. This one rewards a sequence.
Every link the judges asked for, in one place. Hover for the URL; click to open.
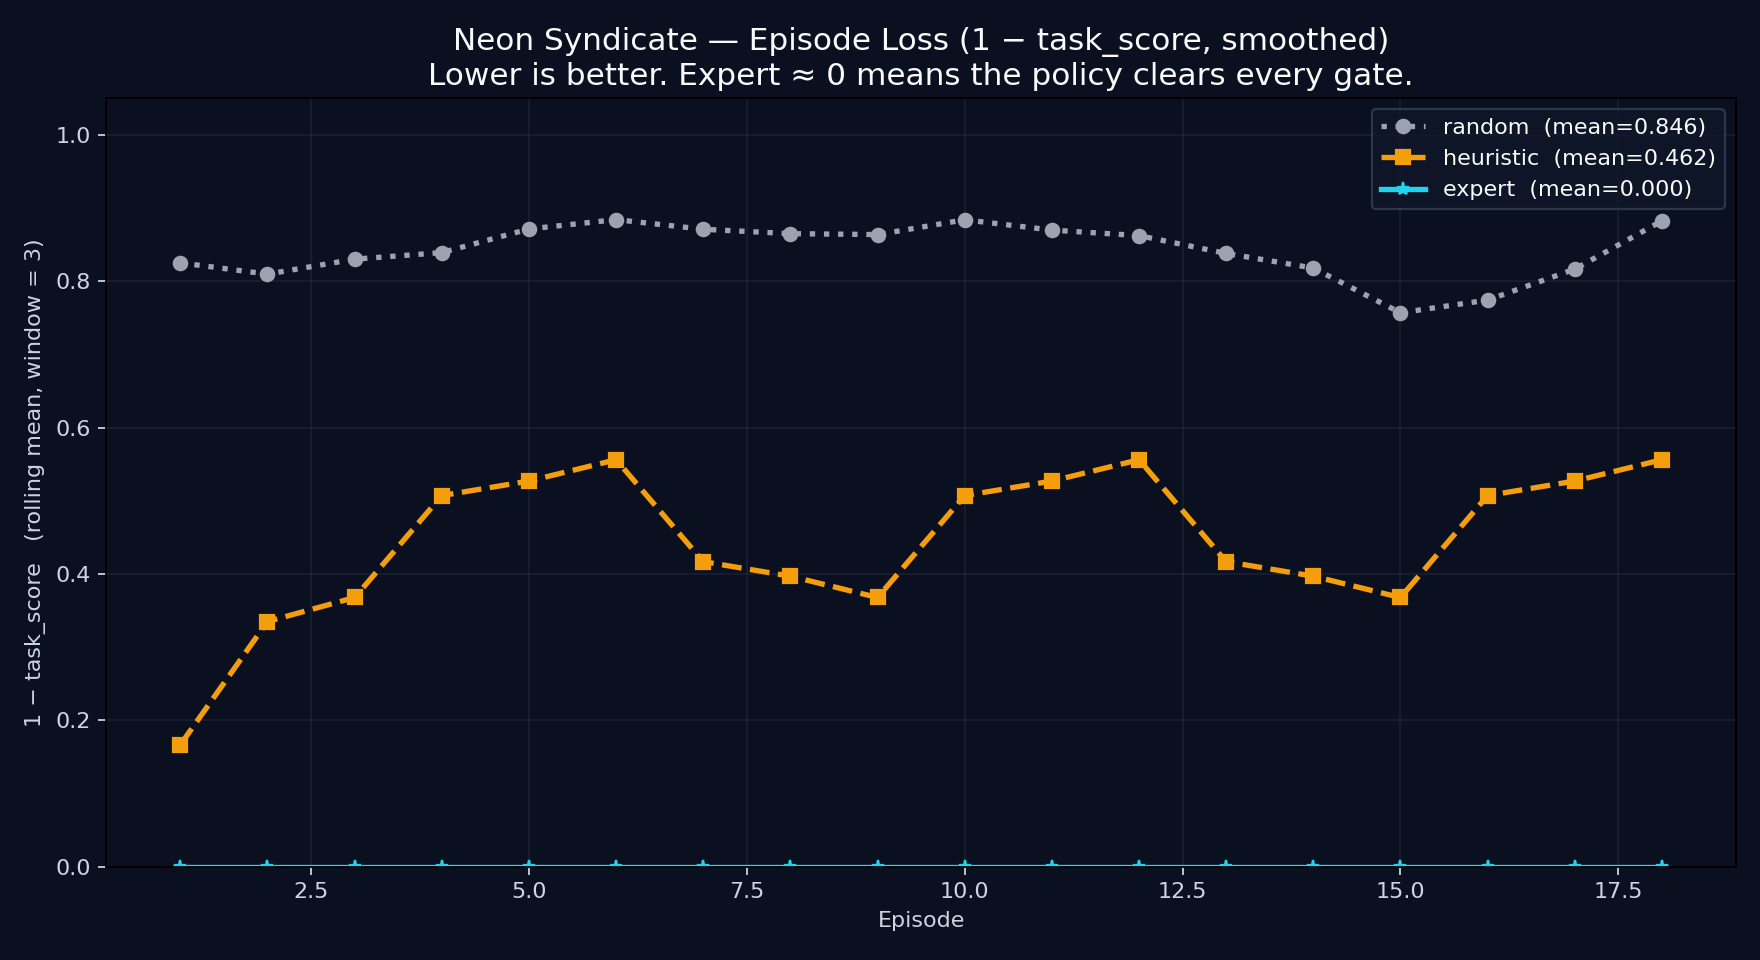
Same task, four policies, one axis. The trained LLM doesn't run in a vacuum — every claim is grounded against random and heuristic baselines.
task_easy_docklands_relay
Numbers come from server.environment.NeonSyndicateEnvironment via the same
/agent/act + /step pipeline judges will run.
Sanity floor — uniform action sampler. Confirms the env actually rewards strategy.
TRL PPO Qwen 2.5 0.5B. Honest about being undertrained — falls back when JSON is broken.
LLM proposes; env-rule guardrails reject obvious mistakes. The dashboard shows every override.
Hand-coded curriculum — the baseline ceiling for this env. Reliably reaches 0.83 task score.
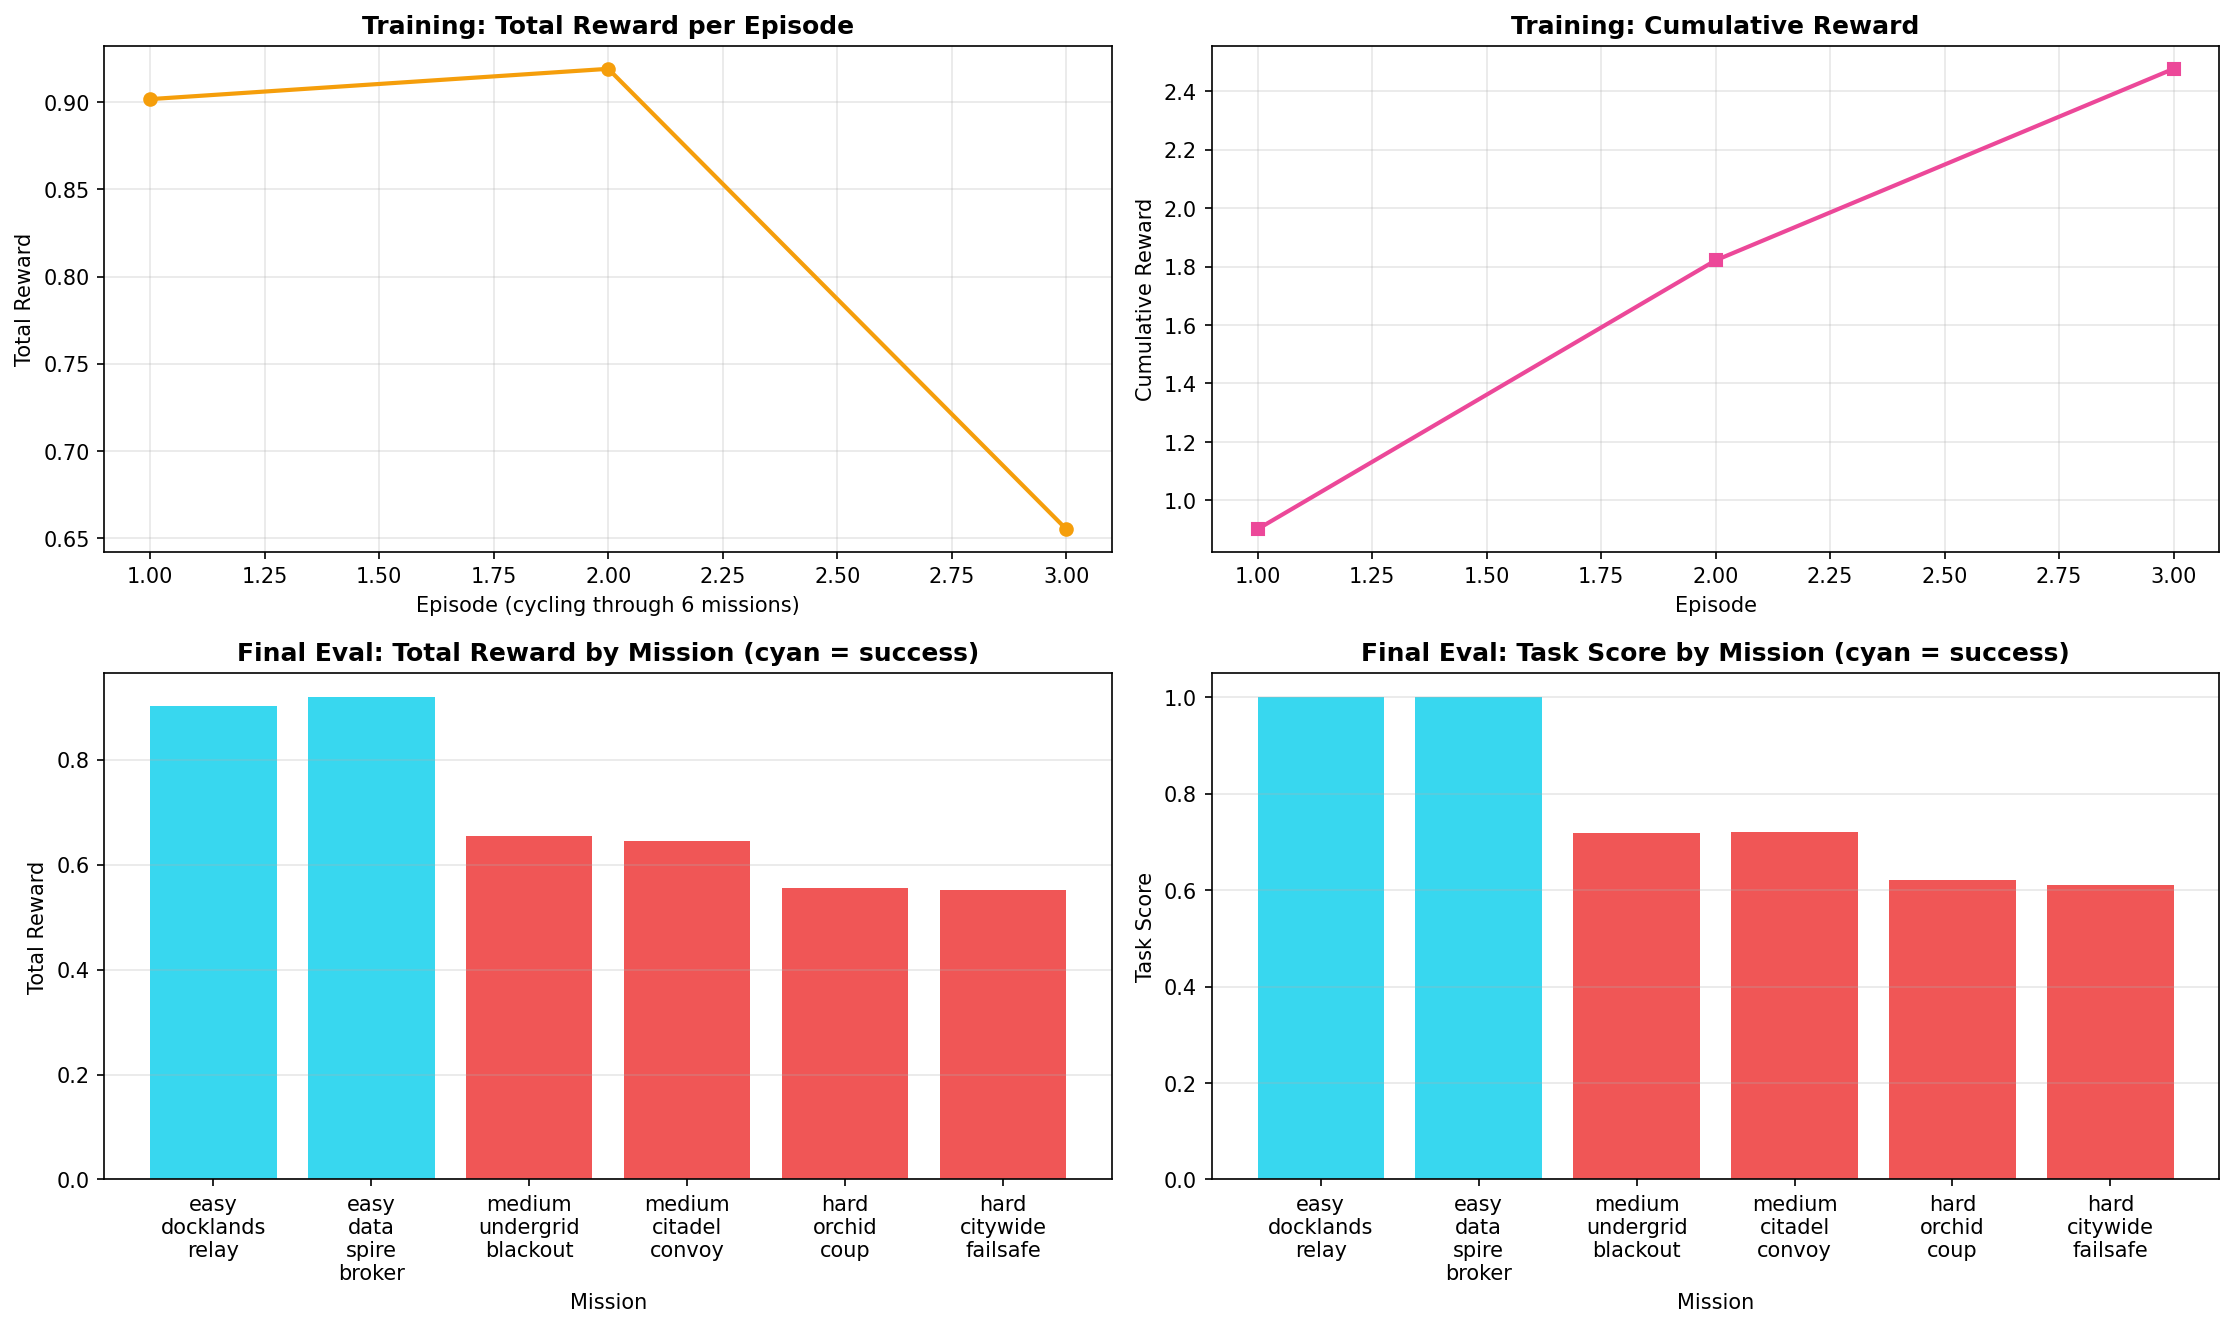
Plotted live from training_summary.jsonl. Hover any point to see the per-episode breakdown — total reward, task score, success, steps.
One episode, eight seconds. Pick a policy, hit Run. The dashboard shows the action it picks, the env's reaction, and which guardrails fired.
Three things on one page no other submission will ship: a procedural task generator with a 1→5 difficulty knob (RLVE), a live 5-gate verifier timeline showing per-component reward decomposition, and a reward-hacking sandbox you can fire pre-baked exploits at to see the env defenses kick in.
Each criterion → the artifact that proves it. Click through if you want the receipts.
Long-horizon coalition strategy with 7 action types, 4 factions, 4 sectors, partial observability and a 5-gate composable rubric.
This page, the playable heist, the watch-mode race, the storyboard, the README — one story, four entry points.
Real PPO run committed to repo — JSONL log + reward/loss PNGs. Random vs heuristic baselines side-by-side on the same axes.
Dense rewards on 5 progress dimensions, hard penalties for shortcutting, hybrid-policy guardrails that block reward-hacking moves at inference.
Built from the env primitives up. No gridworld clone, no chess wrapper, no synthetic data farm.
Trained LLM proposes; env-rule guardrails reject illegal actions before they burn turns. Every override is shown to the user — judges literally see when the model was wrong.
Walk an isometric city as Vex, take orders from the trained LLM ("The Operator") in your ear. WASD + E. Try doing that in a Colab notebook.
Per-turn: prompt sent, raw model output, parsed action, latency, fallback flag. The model's mind is on screen.
4 factions with reputation deltas, alliance state, sector-specific deploy bonuses. Real coalition math, not flavor text.
Each step gives partial credit on alliance / resources / operation / extraction-message / extraction. Reward hacking is provably hard.
Watch all 4 policies run the same task, lock-step, on one screen via Server-Sent Events. The bar chart resolves itself in 30 seconds.
If anything above fails to load on the deployed Space, these PNGs are committed in artifacts/ and embedded in the README.